You read your Chatbot’s last response and it doesn’t sound right. You ask the model to check the results, and it responds with something like “You’re right, I’ve corrected that.” Models are smart, but they aren’t perfect.
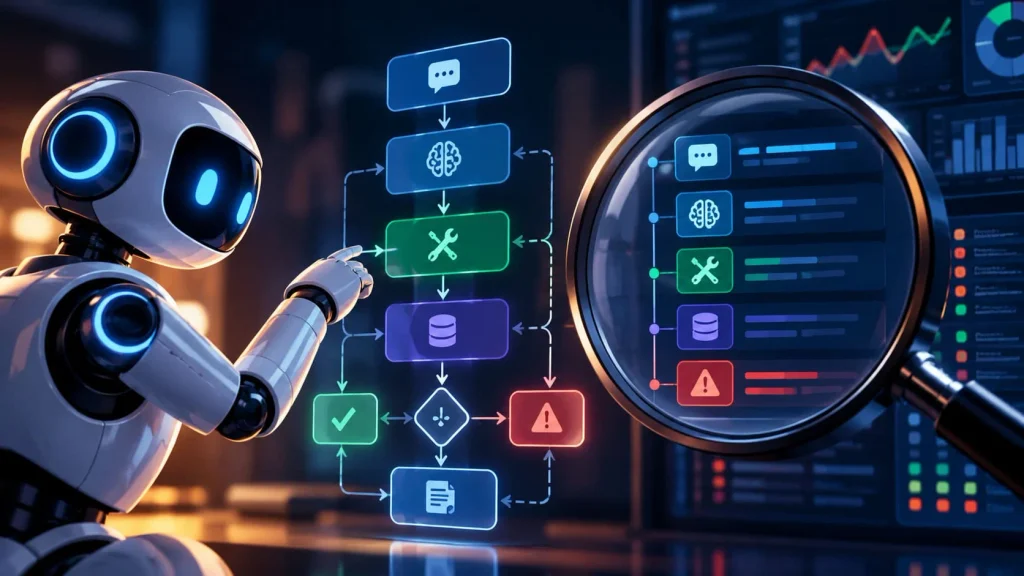
But what happens in a multi-step agentic process where you don’t get the opportunity to check each step? There is no pushback, you never see the errors, you only see the result, which may look plausible. That’s the problem, your agent is a black box, you have no visibility into what is happening at each step. Trustabl’s OTel labels change that, they provide the visibility you need to ensure that your agent is truly reliable and trustworthy. Best of all, your favorite observability tool can process all that data and flag problems for you.
Is this important? Microsoft CEO Satya Nadella is adamant that this is critical: “Every meaningful model action must leave tamper-proof human readable evidence. If it can’t be observed, it can’t be trusted.” He has called for “true aggressive monitoring of agent activity” so there is behavioral evidence and “everything has got to be auditable.” Nadella also argues that the controls governing what a model can access and do must sit outside the model. That is exactly where OTel labels and rule packs live: outside the model and the agent, recording and evaluating every step independently.
What are some problems that can occur, without your knowledge, when the agent’s actions are hidden from view?
1. Tool Loop: Your agent calls the same tool with the same argument multiple times, even though it is giving a correct (often empty) answer. This wastes tokens and time.
2. Retry Storm: Your agent calls the same tool repeatedly, even though the tool is failing each time. You never see the agent thrashing and burning both tokens and time.
3. Answered After Empty Retrieval: The classic silent failure. The agent receives an empty payload, fabricates an answer. You get a reasonable looking answer, but it is a hallucination.
4. Irreversible Action Without a Constraint Decision: Your agent takes a destructive action (delete, charge, publish, send) without any policy check recorded on that step. You have no evidence the action was permitted, and no way to prove it was blocked when it should have been.
5. False Idempotency: Your agent calls a tool that is supposed to return the same result for the same inputs, but the outputs differ. You cannot tell that a “safe” retry or repeated call actually changed something.
6. Handoff Without Policy Binding: Your agent delegates work to a sub-agent, but no signed policy is recorded on that handoff. You cannot prove which rules governed the delegated work, or whether any rules were applied at all.
7. Run Ended by Policy or Step Ceiling: Your agent stops because it hits a hard limit (policy block or maximum steps) rather than because it finished the task. You cannot tell a clean completion from an agent that was cut off.
These are some of the problems that occur in the interactions between your agent and its tools and models. The only way to identify and resolve these issues is by exposing them to the light. OpenTelemetry (OTel) labels are how you expose these to the light. The beauty of these OTel labels is that you can use any observability tool you like, e.g. LangSmith, Langfuse, Datadog, Splunk, Dynatrace, Grafana, OpenLIT, etc.
You might suggest that GenAI already provides those OTel labels, but that set of labels sheds light on the model, not the agent’s internal processes. This is why we created and open-sourced our agentic labels. We aren’t in the observability business, but observability is a critical piece of providing the agent governance control plane. Our goal is to enable your existing tools to see inside your agent’s actions. We took it a step further and built open-source rule packs for some of the leading observability tools, to consume our labels and surface the seven fail states described above.
Additional Reading/Viewing:
Agent Reliability Engineering is the engineering discipline to make agents more reliable in production and observability is a critical component of that.
Check out our agent observability OTel labels and agent OTel rules, use them, and please help us make them better.
When agents behave properly they use fewer tokens, observability is critical to identifying issues and ensuring optimal agent efficiency.
Related Blogs
Agent Reliability Resources